自定义 SQL 代理
冻结参考:显式节点不等于安全 SQL 执行
本页快照于 2026-05-07;其中 provider、模型和图 API 均须以
source的当前文档重新核验。即使图上有查询检查或人工节点,模型生成的 SQL 仍是不可信输入:数据库连接必须最小权限/只读,服务端必须限制对象、语法、成本和结果大小,并对高风险动作应用审批、幂等和审计。不要在笔记或脚本中写入真实 API key、数据库连接串或生产数据。
在本教程中,我们将构建一个自定义代理,它可以使用 LangGraph 回答有关 SQL 数据库的问题。
LangChain 提供内置的 agent 实现,使用 LangGraph 原语实现。如果需要更深入的定制,可以直接在 LangGraph 中实现代理。本指南演示了 SQL 代理的示例实现。有关实际介绍,请参阅使用更高级别的 LangChain 抽象构建 SQL 代理。
Warning
构建 SQL 数据库的问答系统需要执行模型生成的 SQL 查询。这样做存在固有的风险。确保数据库连接权限的范围始终尽可能缩小,以满足代理的需求。这将减轻(但不能消除)构建模型驱动系统的风险。
预构建代理 让我们可以快速入门,但我们依靠系统提示来限制其行为 - 例如,我们指示代理始终从“列表表”工具开始,并始终在执行查询之前运行查询检查器工具。
我们可以通过定制代理来在 LangGraph 中实施更高程度的控制。在这里,我们实现了一个简单的 ReAct-agent 设置,其中包含用于特定工具调用的专用节点。我们将使用与预构建代理相同的 [state]。
概念
我们将涵盖以下概念:
设置
安装
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install langchain  langgraph  langchain-community
LangSmith
设置 LangSmith 来检查您的链或代理内部发生的情况。然后设置以下环境变量:
# 配置环境变量:示例会从环境变量读取 API key、模型名或服务地址。
export LANGSMITH_TRACING="true"
export LANGSMITH_API_KEY="..."
1. 选择LLM
选择支持工具调用的模型:
OpenAI
👉 阅读OpenAI 聊天模型集成文档
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install -U "langchain[openai]"
import os
from langchain.chat_models import init_chat_model
os.environ["OPENAI_API_KEY"] = "sk-..."
# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
model = init_chat_model("gpt-5.4")import os
from langchain_openai import ChatOpenAI
os.environ["OPENAI_API_KEY"] = "sk-..."
# 这里创建具体 provider 的聊天模型对象;保留 provider 名称,便于和官方文档对照。
model = ChatOpenAI(model="gpt-5.4")Anthropic
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install -U "langchain[anthropic]"
import os
from langchain.chat_models import init_chat_model
os.environ["ANTHROPIC_API_KEY"] = "sk-..."
# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
model = init_chat_model("claude-sonnet-4-6")import os
from langchain_anthropic import ChatAnthropic
os.environ["ANTHROPIC_API_KEY"] = "sk-..."
# 这里创建具体 provider 的聊天模型对象;保留 provider 名称,便于和官方文档对照。
model = ChatAnthropic(model="claude-sonnet-4-6")Azure
👉 阅读Azure 聊天模型集成文档
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install -U "langchain[openai]"
import os
from langchain.chat_models import init_chat_model
os.environ["AZURE_OPENAI_API_KEY"] = "..."
os.environ["AZURE_OPENAI_ENDPOINT"] = "..."
os.environ["OPENAI_API_VERSION"] = "2025-03-01-preview"
# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
model = init_chat_model(
"azure_openai:gpt-5.4",
azure_deployment=os.environ["AZURE_OPENAI_DEPLOYMENT_NAME"],
)import os
from langchain_openai import AzureChatOpenAI
os.environ["AZURE_OPENAI_API_KEY"] = "..."
os.environ["AZURE_OPENAI_ENDPOINT"] = "..."
os.environ["OPENAI_API_VERSION"] = "2025-03-01-preview"
model = AzureChatOpenAI(
model="gpt-5.4",
azure_deployment=os.environ["AZURE_OPENAI_DEPLOYMENT_NAME"]
)Google Gemini
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install -U "langchain[google-genai]"
import os
from langchain.chat_models import init_chat_model
os.environ["GOOGLE_API_KEY"] = "..."
# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
model = init_chat_model("google_genai:gemini-2.5-flash-lite")import os
from langchain_google_genai import ChatGoogleGenerativeAI
os.environ["GOOGLE_API_KEY"] = "..."
model = ChatGoogleGenerativeAI(model="gemini-2.5-flash-lite")AWS Bedrock
👉 阅读 AWS Bedrock 聊天模型集成文档
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install -U "langchain[aws]"
from langchain.chat_models import init_chat_model
# 按这里的步骤配置凭据:
# 参考链接:https://docs.aws.amazon.com/bedrock/latest/userguide/getting-started.html
model = init_chat_model(
"anthropic.claude-sonnet-4-6",
model_provider="bedrock_converse",
)from langchain_aws import ChatBedrock
# 这里创建具体 provider 的聊天模型对象;保留 provider 名称,便于和官方文档对照。
model = ChatBedrock(model="anthropic.claude-sonnet-4-6")Hugging Face
👉 阅读 HuggingFace 聊天模型集成文档
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install -U "langchain[huggingface]"
import os
from langchain.chat_models import init_chat_model
os.environ["HUGGINGFACEHUB_API_TOKEN"] = "hf_..."
# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
model = init_chat_model(
"microsoft/Phi-3-mini-4k-instruct",
model_provider="huggingface",
temperature=0.7,
max_tokens=1024,
)import os
from langchain_huggingface import ChatHuggingFace, HuggingFaceEndpoint
os.environ["HUGGINGFACEHUB_API_TOKEN"] = "hf_..."
llm = HuggingFaceEndpoint(
repo_id="microsoft/Phi-3-mini-4k-instruct",
temperature=0.7,
max_length=1024,
)
model = ChatHuggingFace(llm=llm)OpenRouter
# 安装依赖:先把示例需要的包安装到当前 Python 环境。
pip install -U "langchain-openrouter"
import os
from langchain.chat_models import init_chat_model
os.environ["OPENROUTER_API_KEY"] = "sk-..."
# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
model = init_chat_model(
"auto",
model_provider="openrouter",
)import os
from langchain_openrouter import ChatOpenRouter
os.environ["OPENROUTER_API_KEY"] = "sk-..."
model = ChatOpenRouter(model="auto")以下示例中显示的输出使用 OpenAI。
2.配置数据库
您将为本教程创建一个 SQLite 数据库。 SQLite 是一个轻量级数据库,易于设置和使用。我们将加载 chinook 数据库,这是一个代表数字媒体商店的示例数据库。
为方便起见,我们将数据库 (Chinook.db) 托管在公共 GCS 存储桶上。
import requests, pathlib

url = "https://storage.googleapis.com/benchmarks-artifacts/chinook/Chinook.db"
local_path = pathlib.Path("Chinook.db")

if local_path.exists():
    print(f"{local_path} already exists, skipping download.")
else:
    response = requests.get(url)
    if response.status_code == 200:
        local_path.write_bytes(response.content)
        print(f"File downloaded and saved as {local_path}")
    else:
        print(f"Failed to download the file. Status code: {response.status_code}")
我们将使用 langchain_community 包中提供的方便的 SQL 数据库包装器来与数据库交互。包装器提供了一个简单的接口来执行 SQL 查询并获取结果:
from langchain_community.utilities import SQLDatabase

# SQLDatabase 连接示例数据库,后续 SQL agent 会通过 tools 查看 schema 并执行查询。
db = SQLDatabase.from_uri("sqlite:///Chinook.db")

print(f"Dialect: {db.dialect}")
print(f"Available tables: {db.get_usable_table_names()}")
print(f'Sample output: {db.run("SELECT * FROM Artist LIMIT 5;")}')
Dialect: sqlite
Available tables: ['Album', 'Artist', 'Customer', 'Employee', 'Genre', 'Invoice', 'InvoiceLine', 'MediaType', 'Playlist', 'PlaylistTrack', 'Track']
Sample output: [(1, 'AC/DC'), (2, 'Accept'), (3, 'Aerosmith'), (4, 'Alanis Morissette'), (5, 'Alice In Chains')]
3.添加数据库交互工具
使用 langchain_community 包中提供的 SQLDatabase 包装器与数据库交互。包装器提供了一个简单的接口来执行 SQL 查询并获取结果:
from langchain_community.agent_toolkits import SQLDatabaseToolkit

toolkit = SQLDatabaseToolkit(db=db, llm=model)

tools = toolkit.get_tools()

for tool in tools:
    print(f"{tool.name}: {tool.description}\n")
sql_db_query: Input to this tool is a detailed and correct SQL query, output is a result from the database. If the query is not correct, an error message will be returned. If an error is returned, rewrite the query, check the query, and try again. If you encounter an issue with Unknown column 'xxxx' in 'field list', use sql_db_schema to query the correct table fields.
sql_db_schema: Input to this tool is a comma-separated list of tables, output is the schema and sample rows for those tables. Be sure that the tables actually exist by calling sql_db_list_tables first! Example Input: table1, table2, table3
sql_db_list_tables: Input is an empty string, output is a comma-separated list of tables in the database.
sql_db_query_checker: Use this tool to double check if your query is correct before executing it. Always use this tool before executing a query with sql_db_query!
4. 定义申请步骤
我们构建专用节点的步骤如下:
- 列出数据库表
- 调用“获取架构”工具
- 生成查询
- 检查查询
将这些步骤放入专用节点中可以让我们 (1) 在需要时强制调用工具,以及 (2) 自定义与每个步骤相关的提示。
from typing import Literal

from langchain.messages import AIMessage
from langchain_core.runnables import RunnableConfig
from langgraph.graph import END, START, MessagesState, StateGraph
from langgraph.prebuilt import ToolNode

get_schema_tool = next(tool for tool in tools if tool.name == "sql_db_schema")
get_schema_node = ToolNode([get_schema_tool], name="get_schema")

run_query_tool = next(tool for tool in tools if tool.name == "sql_db_query")
run_query_node = ToolNode([run_query_tool], name="run_query")

# 示例:创建一个预先确定的 tool call。
def list_tables(state: MessagesState):
    tool_call = {
        "name": "sql_db_list_tables",
        "args": {},
        "id": "abc123",
        "type": "tool_call",
    }
    tool_call_message = AIMessage(content="", tool_calls=[tool_call])

    list_tables_tool = next(tool for tool in tools if tool.name == "sql_db_list_tables")
    tool_message = list_tables_tool.invoke(tool_call)
    response = AIMessage(f"Available tables: {tool_message.content}")

    return {"messages": [tool_call_message, tool_message, response]}

# 示例:强制模型创建一个 tool call。
def call_get_schema(state: MessagesState):
    # 注意:LangChain 要求所有模型都接受 `tool_choice="any"`。
    # 同时也要接受 `tool_choice=<工具名字符串>`。
    llm_with_tools = model.bind_tools([get_schema_tool], tool_choice="any")
    response = llm_with_tools.invoke(state["messages"])

    return {"messages": [response]}

generate_query_system_prompt = """
You are an agent designed to interact with a SQL database.
Given an input question, create a syntactically correct {dialect} query to run,
then look at the results of the query and return the answer. Unless the user
specifies a specific number of examples they wish to obtain, always limit your
query to at most {top_k} results.

You can order the results by a relevant column to return the most interesting
examples in the database. Never query for all the columns from a specific table,
only ask for the relevant columns given the question.

DO NOT make any DML statements (INSERT, UPDATE, DELETE, DROP etc.) to the database.
""".format(
    dialect=db.dialect,
    top_k=5,
)

def generate_query(state: MessagesState):
    system_message = {
        "role": "system",
        "content": generate_query_system_prompt,
    }
    # 这里不强制 tool 调用,这样模型可以。
    # 在已经得到答案时自然地直接回复。
    llm_with_tools = model.bind_tools([run_query_tool])
    response = llm_with_tools.invoke([system_message] + state["messages"])

    return {"messages": [response]}

check_query_system_prompt = """
You are a SQL expert with a strong attention to detail.
Double check the {dialect} query for common mistakes, including:
- Using NOT IN with NULL values
- Using UNION when UNION ALL should have been used
- Using BETWEEN for exclusive ranges
- Data type mismatch in predicates
- Properly quoting identifiers
- Using the correct number of arguments for functions
- Casting to the correct data type
- Using the proper columns for joins

If there are any of the above mistakes, rewrite the query. If there are no mistakes,
just reproduce the original query.

You will call the appropriate tool to execute the query after running this check.
""".format(dialect=db.dialect)

def check_query(state: MessagesState):
    system_message = {
        "role": "system",
        "content": check_query_system_prompt,
    }

    # 生成一条人工构造的用户消息用于检查。
    tool_call = state["messages"][-1].tool_calls[0]
    user_message = {"role": "user", "content": tool_call["args"]["query"]}
    llm_with_tools = model.bind_tools([run_query_tool], tool_choice="any")
    response = llm_with_tools.invoke([system_message, user_message])
    response.id = state["messages"][-1].id

    return {"messages": [response]}
5. 实施代理
现在,我们可以使用 Graph API 将这些步骤组装到工作流中。我们在查询生成步骤定义一个条件边,如果生成查询,它将路由到查询检查器,或者如果不存在工具调用则结束,以便 LLM 已交付对查询的响应。
def should_continue(state: MessagesState) -> Literal[END, "check_query"]:
    messages = state["messages"]
    last_message = messages[-1]
    if not last_message.tool_calls:
        return END
    else:
        return "check_query"

# StateGraph 用来定义 LangGraph 工作流:node 负责计算,edge 负责控制执行顺序。
builder = StateGraph(MessagesState)
# add_node 注册一个 graph 节点;节点通常接收 state,并返回要写回 state 的局部更新。
builder.add_node(list_tables)
builder.add_node(call_get_schema)
builder.add_node(get_schema_node, "get_schema")
builder.add_node(generate_query)
builder.add_node(check_query)
builder.add_node(run_query_node, "run_query")

# add_edge 定义固定执行顺序,表示一个节点完成后继续运行下一个节点。
builder.add_edge(START, "list_tables")
builder.add_edge("list_tables", "call_get_schema")
builder.add_edge("call_get_schema", "get_schema")
builder.add_edge("get_schema", "generate_query")
# conditional edge 会根据条件函数返回值动态选择下一步节点。
builder.add_conditional_edges(
    "generate_query",
    should_continue,
)
builder.add_edge("check_query", "run_query")
builder.add_edge("run_query", "generate_query")

# compile 会把定义好的 graph/workflow 编译成可执行对象;这里也是接入 checkpointer、store 或 cache 的位置。
agent = builder.compile()
我们将应用程序可视化如下:
from IPython.display import Image, display
from langchain_core.runnables.graph import CurveStyle, MermaidDrawMethod, NodeStyles

display(Image(agent.get_graph().draw_mermaid_png()))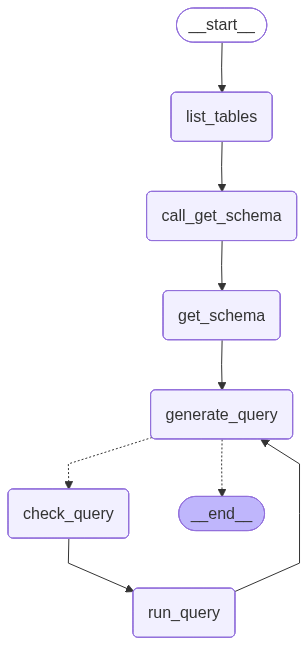
我们现在可以调用该图:
question = "Which genre on average has the longest tracks?"

# 这里是实际运行入口:传入 messages 或 state 后,系统会执行推理、工具调用和状态更新。
for step in agent.stream(
    {"messages": [{"role": "user", "content": question}]},
    stream_mode="values",
):
    step["messages"][-1].pretty_print()
================================ Human Message =================================
Which genre on average has the longest tracks?
================================== Ai Message ==================================
Available tables: Album, Artist, Customer, Employee, Genre, Invoice, InvoiceLine, MediaType, Playlist, PlaylistTrack, Track
================================== Ai Message ==================================
Tool Calls:
sql_db_schema (call_yzje0tj7JK3TEzDx4QnRR3lL)
Call ID: call_yzje0tj7JK3TEzDx4QnRR3lL
Args:
table_names: Genre, Track
================================= Tool Message =================================
Name: sql_db_schema
CREATE TABLE "Genre" (
"GenreId" INTEGER NOT NULL,
"Name" NVARCHAR(120),
PRIMARY KEY ("GenreId")
)
/*
3 rows from Genre table:
GenreId Name
1 Rock
2 Jazz
3 Metal
*/
CREATE TABLE "Track" (
"TrackId" INTEGER NOT NULL,
"Name" NVARCHAR(200) NOT NULL,
"AlbumId" INTEGER,
"MediaTypeId" INTEGER NOT NULL,
"GenreId" INTEGER,
"Composer" NVARCHAR(220),
"Milliseconds" INTEGER NOT NULL,
"Bytes" INTEGER,
"UnitPrice" NUMERIC(10, 2) NOT NULL,
PRIMARY KEY ("TrackId"),
FOREIGN KEY("MediaTypeId") REFERENCES "MediaType" ("MediaTypeId"),
FOREIGN KEY("GenreId") REFERENCES "Genre" ("GenreId"),
FOREIGN KEY("AlbumId") REFERENCES "Album" ("AlbumId")
)
/*
3 rows from Track table:
TrackId Name AlbumId MediaTypeId GenreId Composer Milliseconds Bytes UnitPrice
1 For Those About To Rock (We Salute You) 1 1 1 Angus Young, Malcolm Young, Brian Johnson 343719 11170334 0.99
2 Balls to the Wall 2 2 1 U. Dirkschneider, W. Hoffmann, H. Frank, P. Baltes, S. Kaufmann, G. Hoffmann 342562 5510424 0.99
3 Fast As a Shark 3 2 1 F. Baltes, S. Kaufman, U. Dirkscneider & W. Hoffman 230619 3990994 0.99
*/
================================== Ai Message ==================================
Tool Calls:
sql_db_query (call_cb9ApLfZLSq7CWg6jd0im90b)
Call ID: call_cb9ApLfZLSq7CWg6jd0im90b
Args:
query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgMilliseconds FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.GenreId ORDER BY AvgMilliseconds DESC LIMIT 5;
================================== Ai Message ==================================
Tool Calls:
sql_db_query (call_DMVALfnQ4kJsuF3Yl6jxbeAU)
Call ID: call_DMVALfnQ4kJsuF3Yl6jxbeAU
Args:
query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgMilliseconds FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.GenreId ORDER BY AvgMilliseconds DESC LIMIT 5;
================================= Tool Message =================================
Name: sql_db_query
[('Sci Fi & Fantasy', 2911783.0384615385), ('Science Fiction', 2625549.076923077), ('Drama', 2575283.78125), ('TV Shows', 2145041.0215053763), ('Comedy', 1585263.705882353)]
================================== Ai Message ==================================
The genre with the longest tracks on average is "Sci Fi & Fantasy," with an average track length of approximately 2,911,783 milliseconds. Other genres with relatively long tracks include "Science Fiction," "Drama," "TV Shows," and "Comedy."
Tip
请参阅 LangSmith 跟踪 了解上述运行。
6. 实施人在回路审核
在执行代理的 SQL 查询之前检查是否存在任何意外操作或效率低下,这可能是谨慎的做法。
在这里,我们利用 LangGraph 的 人在回路 功能在执行 SQL 查询之前暂停运行并等待人工审核。使用 LangGraph 的持久层,我们可以无限期地暂停运行(或者至少只要持久层还活着)。
让我们将 sql_db_query 工具包装在接收用户输入的节点中。我们可以使用 interrupt 函数来实现这一点。下面,我们允许输入以批准工具调用、编辑其参数或提供用户反馈。
from langchain_core.runnables import RunnableConfig
from langchain.tools import tool
from langgraph.types import interrupt

# 使用 @tool 可以把普通 Python 函数暴露给 agent,模型会根据函数名、参数和 docstring 判断何时调用。
@tool(
    run_query_tool.name,
    description=run_query_tool.description,
    args_schema=run_query_tool.args_schema
)
def run_query_tool_with_interrupt(config: RunnableConfig, **tool_input):
    request = {
        "action": run_query_tool.name,
        "args": tool_input,
        "description": "Please review the tool call"
    }
    # interrupt 会暂停执行并把请求交给外部人类或 UI,之后用 Command(resume=...) 恢复。
    response = interrupt([request]) # [!code highlight]
    # 批准这次 tool 调用。
    if response["type"] == "accept":
        tool_response = run_query_tool.invoke(tool_input, config)
    # 更新 tool 调用参数。
    elif response["type"] == "edit":
        tool_input = response["args"]["args"]
        tool_response = run_query_tool.invoke(tool_input, config)
    # 把用户反馈返回给 LLM。
    elif response["type"] == "response":
        user_feedback = response["args"]
        tool_response = user_feedback
    else:
        raise ValueError(f"Unsupported interrupt response type: {response['type']}")

    return tool_response

# 重新定义 tool node,使其使用带 interrupt 的版本。
run_query_node = ToolNode([run_query_tool_with_interrupt], name="run_query") # [!code highlight]
Note
上述实现遵循更广泛的人在回路 指南中的工具中断示例。有关详细信息和替代方案,请参阅该指南。
现在让我们重新组装我们的图。我们将用人工审核取代程序检查。请注意,我们现在包含一个 checkpointer;这是暂停和恢复运行所必需的。
from langgraph.checkpoint.memory import InMemorySaver

def should_continue(state: MessagesState) -> Literal[END, "run_query"]:
    messages = state["messages"]
    last_message = messages[-1]
    if not last_message.tool_calls:
        return END
    else:
        return "run_query"

# StateGraph 用来定义 LangGraph 工作流:node 负责计算,edge 负责控制执行顺序。
builder = StateGraph(MessagesState)
# add_node 注册一个 graph 节点;节点通常接收 state,并返回要写回 state 的局部更新。
builder.add_node(list_tables)
builder.add_node(call_get_schema)
builder.add_node(get_schema_node, "get_schema")
builder.add_node(generate_query)
builder.add_node(run_query_node, "run_query")

# add_edge 定义固定执行顺序,表示一个节点完成后继续运行下一个节点。
builder.add_edge(START, "list_tables")
builder.add_edge("list_tables", "call_get_schema")
builder.add_edge("call_get_schema", "get_schema")
builder.add_edge("get_schema", "generate_query")
# conditional edge 会根据条件函数返回值动态选择下一步节点。
builder.add_conditional_edges(
    "generate_query",
    should_continue,
)
builder.add_edge("run_query", "generate_query")

# checkpointer 保存线程内的执行状态,用于多轮对话、暂停恢复和 human-in-the-loop。
checkpointer = InMemorySaver() # [!code highlight]
agent = builder.compile(checkpointer=checkpointer) # [!code highlight]
我们可以像以前一样调用该图。这次,执行被中断:
import json

config = {"configurable": {"thread_id": "1"}}

question = "Which genre on average has the longest tracks?"

# 这里是实际运行入口:传入 messages 或 state 后,系统会执行推理、工具调用和状态更新。
for step in agent.stream(
    {"messages": [{"role": "user", "content": question}]},
    config,
    stream_mode="values",
):
    if "messages" in step:
        step["messages"][-1].pretty_print()
    elif "__interrupt__" in step:
        action = step["__interrupt__"][0]
        print("INTERRUPTED:")
        for request in action.value:
            print(json.dumps(request, indent=2))
    else:
        pass
...
INTERRUPTED:
{
"action": "sql_db_query",
"args": {
"query": "SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgLength FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.Name ORDER BY AvgLength DESC LIMIT 5;"
},
"description": "Please review the tool call"
}
我们可以使用 Command 接受或编辑工具调用:
from langgraph.types import Command

# 这里是实际运行入口:传入 messages 或 state 后,系统会执行推理、工具调用和状态更新。
for step in agent.stream(
    # Command 可以同时表达 state 更新和下一步跳转,适合工具返回后改变流程的场景。
    Command(resume={"type": "accept"}),
    # 示例:用 Command(resume=...) 恢复执行,并传入编辑后的参数。
    config,
    stream_mode="values",
):
    if "messages" in step:
        step["messages"][-1].pretty_print()
    elif "__interrupt__" in step:
        action = step["__interrupt__"][0]
        print("INTERRUPTED:")
        for request in action.value:
            print(json.dumps(request, indent=2))
    else:
        pass
================================== Ai Message ==================================
Tool Calls:
sql_db_query (call_t4yXkD6shwdTPuelXEmY3sAY)
Call ID: call_t4yXkD6shwdTPuelXEmY3sAY
Args:
query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgLength FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.Name ORDER BY AvgLength DESC LIMIT 5;
================================= Tool Message =================================
Name: sql_db_query
[('Sci Fi & Fantasy', 2911783.0384615385), ('Science Fiction', 2625549.076923077), ('Drama', 2575283.78125), ('TV Shows', 2145041.0215053763), ('Comedy', 1585263.705882353)]
================================== Ai Message ==================================
The genre with the longest average track length is "Sci Fi & Fantasy" with an average length of about 2,911,783 milliseconds. Other genres with long average track lengths include "Science Fiction," "Drama," "TV Shows," and "Comedy."
有关详细信息,请参阅人在回路指南。
后续步骤
查看 评估图 指南,以使用 LangSmith 评估 LangGraph 应用程序,包括像这样的 SQL 代理。