自定义 RAG 代理
冻结参考:图代码只用于理解拓扑
这是 2026-05-07 的来源快照,示例会联网下载资料、要求 provider 凭据并依赖当时的 LangChain/LangGraph 集成 API。它不能证明当前图定义、检索质量、引用可追溯性、租户过滤或恢复策略正确。先用 当前 RAG 组件课程 建立检索合同;只有确实需要显式分支/状态时,再按 LangGraph 边界 和本页
source的当前版本重建。
概述
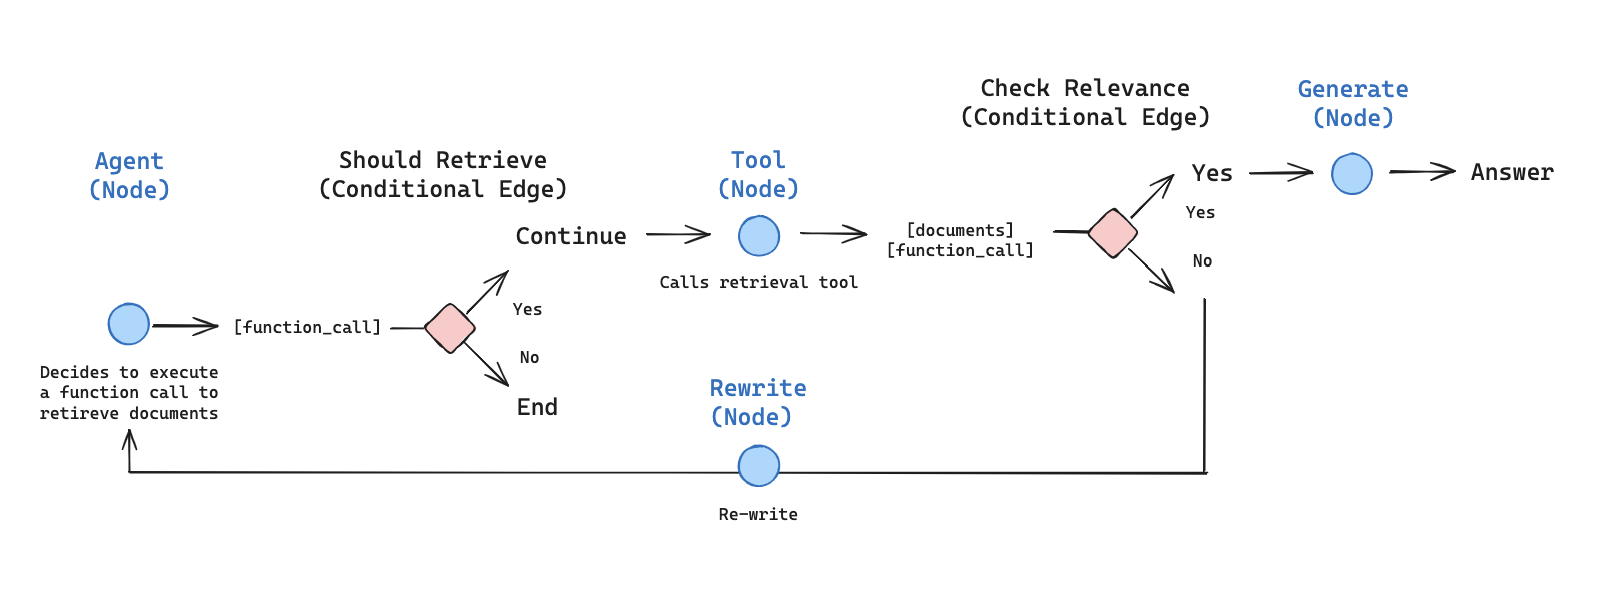
在本教程中,我们将使用 LangGraph 构建一个 检索 代理。
LangChain 提供内置的 agent 实现,使用 LangGraph 原语实现。如果需要更深入的定制,可以直接在 LangGraph 中实现代理。本指南演示了检索代理的示例实现。当您希望 LLM 决定是从向量存储中检索上下文还是直接响应用户时,检索 代理非常有用。
在本教程结束时,我们将完成以下操作:
- 获取并预处理将用于检索的文档。
- 为这些文档建立索引以进行语义搜索,并为代理创建检索器工具。
- 构建一个代理 RAG 系统,可以决定何时使用检索器工具。
概念
我们将涵盖以下概念:
设置
让我们下载所需的包并设置 API 密钥:
pip install -U langgraph "langchain[openai]" langchain-community langchain-text-splitters bs4import getpass
import os
def _set_env(key: str):
if key not in os.environ:
os.environ[key] = getpass.getpass(f"{key}:")
_set_env("OPENAI_API_KEY")Tip
注册 LangSmith 以快速发现问题并提高 LangGraph 项目的性能。 LangSmith 可让您使用跟踪数据来调试、测试和监控使用 LangGraph 构建的 LLM 应用程序。
1. 预处理文档
- 获取要在我们的 RAG 系统中使用的文档。我们将使用Lilian Weng 的优秀博客 中的三个最新页面。我们首先使用
WebBaseLoader实用程序获取页面内容:
from langchain_community.document_loaders import WebBaseLoader

urls = [
    "https://lilianweng.github.io/posts/2024-11-28-reward-hacking/",
    "https://lilianweng.github.io/posts/2024-07-07-hallucination/",
    "https://lilianweng.github.io/posts/2024-04-12-diffusion-video/",
]

# 加载和切分阶段会把长资料拆成较小 chunk,方便 embedding 和检索。
docs = [WebBaseLoader(url).load() for url in urls]docs[0][0].page_content.strip()[:1000]- 将获取的文档分割成更小的块,以便索引到我们的向量存储中:
from langchain_text_splitters import RecursiveCharacterTextSplitter

docs_list = [item for sublist in docs for item in sublist]

text_splitter = RecursiveCharacterTextSplitter.from_tiktoken_encoder(
    chunk_size=100, chunk_overlap=50
)
# 加载和切分阶段会把长资料拆成较小 chunk,方便 embedding 和检索。
doc_splits = text_splitter.split_documents(docs_list)doc_splits[0].page_content.strip()2. 创建检索工具
现在我们有了分割文档,我们可以将它们索引到向量存储中,用于语义搜索。
- 使用记忆向量存储和 OpenAI 嵌入:
from langchain_core.vectorstores import InMemoryVectorStore
from langchain_openai import OpenAIEmbeddings

# vector store 用来保存文本向量和元数据,查询时按语义相似度找回相关片段。
vectorstore = InMemoryVectorStore.from_documents(
    # embedding 模型会把文本转换成向量,这是 semantic search 和 RAG 检索的基础。
    documents=doc_splits, embedding=OpenAIEmbeddings()
)
# retriever 是检索器,负责根据用户问题从资料库中取回候选文档。
retriever = vectorstore.as_retriever()- 使用
@tool装饰器创建一个检索器工具:
from langchain.tools import tool

# 使用 @tool 可以把普通 Python 函数暴露给 agent,模型会根据函数名、参数和 docstring 判断何时调用。
@tool
def retrieve_blog_posts(query: str) -> str:
    """Search and return information about Lilian Weng blog posts."""
    docs = retriever.invoke(query)
    return "\n\n".join([doc.page_content for doc in docs])

retriever_tool = retrieve_blog_posts- 测试工具:
retriever_tool.invoke({"query": "types of reward hacking"})3. 生成查询
请注意,组件将在 MessagesState 上运行 - 图状态包含 messages 键和聊天消息 列表。
- 构建一个
generate_query_or_respond节点。它将调用 LLM 根据当前图状态(消息列表)生成响应。给定输入消息,它将决定使用检索器工具进行检索,或直接响应用户。请注意,我们为聊天模型提供了对我们之前通过.bind_tools创建的retriever_tool的访问权限:
from langgraph.graph import MessagesState
from langchain.chat_models import init_chat_model

# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
response_model = init_chat_model("gpt-5.4", temperature=0)

def generate_query_or_respond(state: MessagesState):
    """Call the model to generate a response based on the current state. Given
    the question, it will decide to retrieve using the retriever tool, or simply respond to the user.
    """
    response = (
        response_model
        .bind_tools([retriever_tool]).invoke(state["messages"])  # [!code highlight]
    )
return {"messages": [response]}- 尝试随机输入:
input = {"messages": [{"role": "user", "content": "hello!"}]}
generate_query_or_respond(input)["messages"][-1].pretty_print()
输出:
================================== Ai Message ==================================

Hello! How can I help you today?
- 提出一个需要语义搜索的问题:
input = {
    "messages": [
        {
            "role": "user",
            "content": "What does Lilian Weng say about types of reward hacking?",
        }
    ]
}
generate_query_or_respond(input)["messages"][-1].pretty_print()
输出:
================================== Ai Message ==================================
Tool Calls:
retrieve_blog_posts (call_tYQxgfIlnQUDMdtAhdbXNwIM)
Call ID: call_tYQxgfIlnQUDMdtAhdbXNwIM
Args:
    query: types of reward hacking
4. 成绩文件
- 添加条件边—
grade_documents—以确定检索到的文档是否与问题相关。我们将使用具有结构化输出 schemaGradeDocuments的模型进行文档分级。grade_documents函数将根据评分决策返回要转到的节点的名称(generate_answer或rewrite_question):
from pydantic import BaseModel, Field
from typing import Literal

GRADE_PROMPT = (
    "You are a grader assessing relevance of a retrieved document to a user question. \n "
    "Here is the retrieved document: \n\n {context} \n\n"
    "Here is the user question: {question} \n"
    "If the document contains keyword(s) or semantic meaning related to the user question, grade it as relevant. \n"
    "Give a binary score 'yes' or 'no' score to indicate whether the document is relevant to the question."
)

class GradeDocuments(BaseModel):  # [!code highlight]
    """Grade documents using a binary score for relevance check."""

    binary_score: str = Field(
        description="Relevance score: 'yes' if relevant, or 'no' if not relevant"
    )

# 初始化 chat model:后续 agent、chain 或 graph 都会通过这个模型向 LLM 发请求。
grader_model = init_chat_model("gpt-5.4", temperature=0)

def grade_documents(
    state: MessagesState,
) -> Literal["generate_answer", "rewrite_question"]:
    """Determine whether the retrieved documents are relevant to the question."""
    question = state["messages"][0].content
    context = state["messages"][-1].content

    prompt = GRADE_PROMPT.format(question=question, context=context)
    response = (
        grader_model
        # with_structured_output 要求模型按指定 schema 返回结构化结果,后续代码可以稳定读取字段。
        .with_structured_output(GradeDocuments).invoke(  # [!code highlight]
            [{"role": "user", "content": prompt}]
        )
    )
    score = response.binary_score

    if score == "yes":
        return "generate_answer"
    else:
return "rewrite_question"- 使用工具响应中不相关的文档运行此命令:
from langchain_core.messages import convert_to_messages

input = {
    "messages": convert_to_messages(
        [
            {
                "role": "user",
                "content": "What does Lilian Weng say about types of reward hacking?",
            },
            {
                "role": "assistant",
                "content": "",
                "tool_calls": [
                    {
                        "id": "1",
                        "name": "retrieve_blog_posts",
                        "args": {"query": "types of reward hacking"},
                    }
                ],
            },
            {"role": "tool", "content": "meow", "tool_call_id": "1"},
        ]
    )
}
grade_documents(input)- 确认相关文件的分类如下:
input = {
    "messages": convert_to_messages(
        [
            {
                "role": "user",
                "content": "What does Lilian Weng say about types of reward hacking?",
            },
            {
                "role": "assistant",
                "content": "",
                "tool_calls": [
                    {
                        "id": "1",
                        "name": "retrieve_blog_posts",
                        "args": {"query": "types of reward hacking"},
                    }
                ],
            },
            {
                "role": "tool",
                "content": "reward hacking can be categorized into two types: environment or goal misspecification, and reward tampering",
                "tool_call_id": "1",
            },
        ]
    )
}
grade_documents(input)
5.重写问题
- 构建
rewrite_question节点。检索器工具可能返回潜在不相关的文档,这表明需要改进原始用户问题。为此,我们将调用rewrite_question节点:
from langchain.messages import HumanMessage

REWRITE_PROMPT = (
    "Look at the input and try to reason about the underlying semantic intent / meaning.\n"
    "Here is the initial question:"
    "\n ------- \n"
    "{question}"
    "\n ------- \n"
    "Formulate an improved question:"
)

def rewrite_question(state: MessagesState):
    """Rewrite the original user question."""
    messages = state["messages"]
    question = messages[0].content
    prompt = REWRITE_PROMPT.format(question=question)
    response = response_model.invoke([{"role": "user", "content": prompt}])
return {"messages": [HumanMessage(content=response.content)]}- 尝试一下:
input = {
    "messages": convert_to_messages(
        [
            {
                "role": "user",
                "content": "What does Lilian Weng say about types of reward hacking?",
            },
            {
                "role": "assistant",
                "content": "",
                "tool_calls": [
                    {
                        "id": "1",
                        "name": "retrieve_blog_posts",
                        "args": {"query": "types of reward hacking"},
                    }
                ],
            },
            {"role": "tool", "content": "meow", "tool_call_id": "1"},
        ]
    )
}

response = rewrite_question(input)
print(response["messages"][-1].content)
输出:
What are the different types of reward hacking described by Lilian Weng, and how does she explain them?
6. 生成答案
- 构建
generate_answer节点:如果我们通过了评分者检查,我们可以根据原始问题和检索到的上下文生成最终答案:
GENERATE_PROMPT = (
    "You are an assistant for question-answering tasks. "
    "Use the following pieces of retrieved context to answer the question. "
    "If you don't know the answer, just say that you don't know. "
    "Use three sentences maximum and keep the answer concise.\n"
    "Question: {question} \n"
    "Context: {context}"
)

def generate_answer(state: MessagesState):
    """Generate an answer."""
    question = state["messages"][0].content
    context = state["messages"][-1].content
    prompt = GENERATE_PROMPT.format(question=question, context=context)
    response = response_model.invoke([{"role": "user", "content": prompt}])
return {"messages": [response]}- 尝试一下:
input = {
    "messages": convert_to_messages(
        [
            {
                "role": "user",
                "content": "What does Lilian Weng say about types of reward hacking?",
            },
            {
                "role": "assistant",
                "content": "",
                "tool_calls": [
                    {
                        "id": "1",
                        "name": "retrieve_blog_posts",
                        "args": {"query": "types of reward hacking"},
                    }
                ],
            },
            {
                "role": "tool",
                "content": "reward hacking can be categorized into two types: environment or goal misspecification, and reward tampering",
                "tool_call_id": "1",
            },
        ]
    )
}

response = generate_answer(input)
response["messages"][-1].pretty_print()
输出:
================================== Ai Message ==================================

Lilian Weng categorizes reward hacking into two types: environment or goal misspecification, and reward tampering. She considers reward hacking as a broad concept that includes both of these categories. Reward hacking occurs when an agent exploits flaws or ambiguities in the reward function to achieve high rewards without performing the intended behaviors.
7. 组装图
现在我们将把所有的节点和边组装成一个完整的图:
- 从
generate_query_or_respond开始并确定是否需要调用retriever_tool - 使用
tools_condition路由到下一步:- 如果
generate_query_or_respond返回tool_calls,则调用retriever_tool来检索上下文 - 否则直接回复用户
- 如果
- 对检索到的文档内容与问题 (
grade_documents) 的相关性进行评分并进入下一步:- 如果不相关,请使用
rewrite_question重写问题,然后再次调用generate_query_or_respond - 如果相关,请继续进行
generate_answer并使用ToolMessage和检索到的文档上下文生成最终响应
- 如果不相关,请使用
from langgraph.graph import StateGraph, START, END
from langgraph.prebuilt import ToolNode, tools_condition

# StateGraph 用来定义 LangGraph 工作流:node 负责计算,edge 负责控制执行顺序。
workflow = StateGraph(MessagesState)

# 定义将在循环中反复执行的节点。
workflow.add_node(generate_query_or_respond)
workflow.add_node("retrieve", ToolNode([retriever_tool]))
workflow.add_node(rewrite_question)
workflow.add_node(generate_answer)

# add_edge 定义固定执行顺序,表示一个节点完成后继续运行下一个节点。
workflow.add_edge(START, "generate_query_or_respond")

# 判断是否需要先检索资料。
workflow.add_conditional_edges(
    "generate_query_or_respond",
    # 评估 LLM 决策:是调用 `retriever_tool`,还是直接回复用户。
    tools_condition,
    {
        # 把条件函数的输出映射到 graph 中的节点。
        "tools": "retrieve",
        END: END,
    },
)

# `action` 节点执行后会沿这些边继续运行。
workflow.add_conditional_edges(
    "retrieve",
    # 评估 agent 的决策。
    grade_documents,
)
workflow.add_edge("generate_answer", END)
workflow.add_edge("rewrite_question", "generate_query_or_respond")

# 编译 graph,得到可运行对象。
graph = workflow.compile()
可视化图:
from IPython.display import Image, display

display(Image(graph.get_graph().draw_mermaid_png()))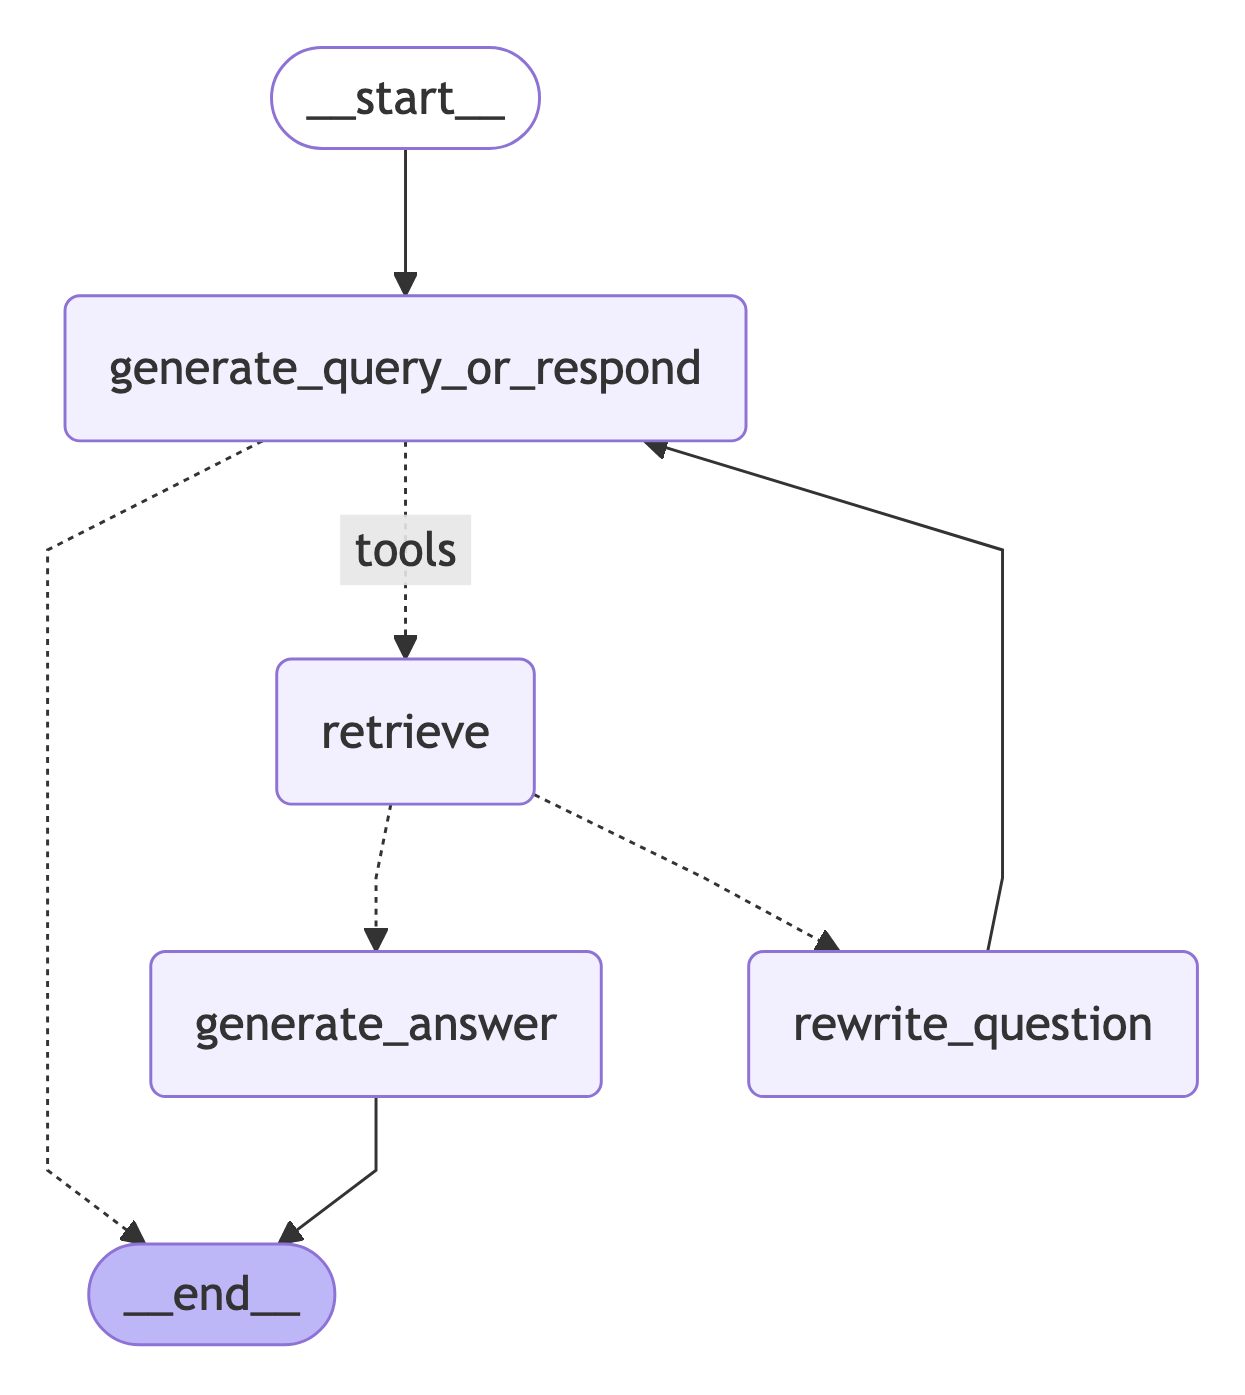
8. 运行代理 RAG
现在让我们通过一个问题来运行它来测试完整的图:
# 这里是实际运行入口:传入 messages 或 state 后,系统会执行推理、工具调用和状态更新。
for chunk in graph.stream(
    {
        "messages": [
            {
                "role": "user",
                "content": "What does Lilian Weng say about types of reward hacking?",
            }
        ]
    }
):
    for node, update in chunk.items():
        print("Update from node", node)
        update["messages"][-1].pretty_print()
        print("\n\n")
输出:
Update from node generate_query_or_respond
================================== Ai Message ==================================
Tool Calls:
  retrieve_blog_posts (call_NYu2vq4km9nNNEFqJwefWKu1)
 Call ID: call_NYu2vq4km9nNNEFqJwefWKu1
  Args:
    query: types of reward hacking

Update from node retrieve
================================= Tool Message ==================================
Name: retrieve_blog_posts

(Note: Some work defines reward tampering as a distinct category of misalignment behavior from reward hacking. But I consider reward hacking as a broader concept here.)
At a high level, reward hacking can be categorized into two types: environment or goal misspecification, and reward tampering.

Why does Reward Hacking Exist?#

Pan et al. (2022) investigated reward hacking as a function of agent capabilities, including (1) model size, (2) action space resolution, (3) observation space noise, and (4) training time. They also proposed a taxonomy of three types of misspecified proxy rewards:

Let's Define Reward Hacking#
Reward shaping in RL is challenging. Reward hacking occurs when an RL agent exploits flaws or ambiguities in the reward function to obtain high rewards without genuinely learning the intended behaviors or completing the task as designed. In recent years, several related concepts have been proposed, all referring to some form of reward hacking:

Update from node generate_answer
================================== Ai Message ==================================

Lilian Weng categorizes reward hacking into two types: environment or goal misspecification, and reward tampering. She considers reward hacking as a broad concept that includes both of these categories. Reward hacking occurs when an agent exploits flaws or ambiguities in the reward function to achieve high rewards without performing the intended behaviors.